powershelldba.de · Uwe Janke
REF: PSDB-SQMDT-2026 SCOPE: SQL Server 2016+ STATUS: Production
Module

Move table data between instances without losing the constraints, or the proof.

sqmDataTransfer is a dbatools-based PowerShell module that copies chosen tables from one SQL Server instance to another: it can script the table's DDL on the target if it doesn't exist yet, disables foreign keys and non-clustered indexes for the bulk copy, re-enables them afterward, guaranteed, even on failure, and reconciles row counts between source and target. Every run writes a full log and a self-contained HTML report.

Why this exists

"Just BCP it over" skips the parts that actually go wrong.

Moving table data between instances by hand means separately handling the target DDL, disabling constraints so the bulk load doesn't choke on FK checks, remembering to re-enable everything afterward even if step 3 fails, and then manually counting rows to prove nothing was lost. sqmDataTransfer runs that whole sequence as one call.

Without itWith sqmDataTransfer
Target table DDL scripted and re-typed by hand, dependencies missedTable, dependent types, sequences, and FK-referenced tables scripted automatically
Bulk copy fails or crawls because FKs/indexes are still activeNon-clustered indexes and foreign keys disabled for the copy, every time
A failed step leaves constraints disabled with no one noticingRe-enable runs in a finally block, guaranteed, even after a failure
"I think it copied everything", no proofExplicit source-vs-target row-count comparison in the report
Partitioned or CLR-typed tables fail the script with an opaque errorPartitioning stripped with a warning; CLR types flagged for manual assembly deploy
A 220-table overnight run gets killed halfway, no idea what's already done-SkipCompleted re-derives that from actual row counts and resumes only what's left
A 300M-row table with no primary key can't resume a killed copy without recopying everythingInvoke-sqmChunkedTableTransfer resumes per chunk by row count, no key required
Verifying the copy means a full COUNT(*) scan on both sidesRow counts read from SQL Server's own partition metadata, no scan, safe at any table size
What one call does

Five steps, run in order, logged individually.

Invoke-sqmTableTransfer is the main entry point, it orchestrates the full sequence below for every table you pass in.

  1. Script metadata (optional)Scripts the table DDL, columns, PK, indexes, foreign keys, defaults, checks, from the source and creates it on the target if it doesn't already exist. Existing target tables are never dropped or recreated.
  2. DisableDisables foreign keys, non-clustered indexes, and DML triggers on the target table so the bulk load isn't fighting constraint checks, index maintenance, or a trigger firing per row.
  3. Copy dataBulk-copies rows from source to target via dbatools' Copy-DbaDbTableData.
  4. Compare row countsCounts rows on both sides and records the comparison in the report.
  5. Re-enableRebuilds the disabled foreign keys and indexes, inside a finally block, so this step runs even if an earlier one fails.

Every step is logged to %LogPath%\sqmDataTransfer_yyyyMMdd_<FunctionName>.log and returned as a structured result object (Table, Step, Status, Message, Timestamp). A self-contained HTML report is always written at the end of the run, every processed table, anything missing or failed, and the row-count comparison, and opens automatically in the browser unless -NoOpen is passed.

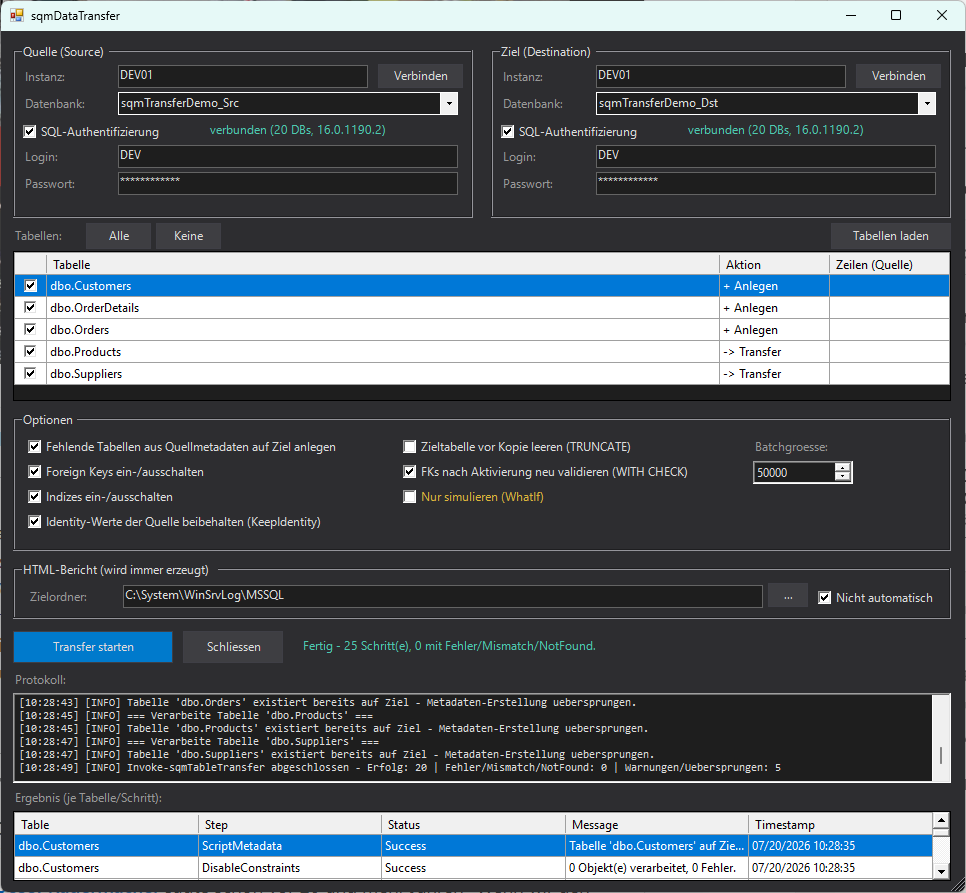
Show-sqmTableTransferGui window connected to a source and a destination SQL Server instance, with five tables loaded: dbo.Customers, dbo.OrderDetails, and dbo.Orders marked '+ Anlegen' because they don't exist yet on the target, dbo.Products and dbo.Suppliers marked '-> Transfer' because they already do. The options panel has metadata scripting, foreign key and index handling, and KeepIdentity all enabled. The status bar reads 'Fertig - 25 Schritt(e), 0 mit Fehler/Mismatch/NotFound', with the protocol log and the per-table/per-step result grid populated below it.
The GUI after a real run: three tables scripted and created from source metadata, two already present and just transferred, all 25 steps (5 tables × 5 steps) succeeded.

Resuming an interrupted run

A run over hundreds of tables can get killed halfway, a crashed session, a rebooted box overnight, and the HTML report is only written once the run finishes, so there's normally no record of what actually made it. -SkipCompleted runs Compare-sqmTableRowCount against every requested table up front and skips any where source and target row counts already match, so re-submitting the full table list only touches what's still outstanding. No separate bookkeeping of "which tables finished", completeness is re-derived from the data itself, every time. Available on Invoke-sqmTableTransfer and as a checkbox in the GUI's options panel.

Metadata scripting

The part that usually breaks a hand-written CREATE TABLE.

With -ScriptMetadata, the module doesn't just script the table, it walks the real dependency graph so the CREATE actually succeeds on the target.

SchemaThe destination schema is created automatically if it doesn't exist
DependenciesUser-defined types, sequences, and FK-referenced tables the table depends on are scripted automatically too (SMO WithDependencies)
Partitioned tablesStill fully scripted and transferred, but the physical partitioning itself (partition function/scheme, per-partition filegroups) is stripped, since there's no way to know whether an equivalent scheme exists on the target. Lands as a normal table on PRIMARY instead of failing with a missing-partition-scheme error. Reported as a warning.
CLR user-defined typesScripted, but flagged as a warning, the assembly itself has to be deployed on the target manually
Version targetingThe destination's actual SQL Server version is auto-detected and passed to SMO as TargetServerVersion, so scripting from a newer source (e.g. 2022) down to an older target (e.g. 2019) produces syntax the target can run
For the tables that don't fit in one copy

Hundreds of millions of rows, no primary key, resumable anyway.

Invoke-sqmTableTransfer is all-or-nothing: if a copy of a 300-million-row table is interrupted an hour in, there's normally no reliable way to know which rows already made it across without a key to anti-join on, and no way to resume without re-copying everything. Invoke-sqmChunkedTableTransfer splits the table by a discriminating column (typically a reporting or snapshot date) and transfers it one distinct value, or one calendar month, at a time instead.

ResumabilitySource and destination row counts per chunk value are snapshotted once, up front, in a single GROUP BY scan per side, not re-queried per chunk. A chunk whose counts already match is skipped, a re-run after a partial failure only touches what's left, with no primary/unique key required anywhere on the table.
Interrupted mid-chunkIf a chunk is killed mid-copy (not between chunks), whatever leftover rows already landed for that one chunk are deleted before it's retried, so a retry can never double up rows, even without a key to prevent duplicates.
Automatic chunk column-ChunkColumn is optional. Get-sqmChunkColumnCandidate ranks date-typed and period-named columns by naming convention and estimates each candidate's chunk count from the column's statistics histogram, a metadata read that costs the same on a 344-million-row table as on an empty one. INT, BIGINT, CHAR or VARCHAR columns holding dates as YYYYMMDD (e.g. 20260115) are recognised too, whatever they are called: every key of their statistics histogram is a valid date. The choice, its estimate, and the reason are logged; with no suitable candidate the run aborts and names what it rejected and why, instead of guessing.
Month granularityA day-level column would mean one chunk per day, thousands of tiny chunks over a few years. -ChunkGranularity Auto (the default) switches day-level columns, YYYYMMDD surrogates and date columns with clearly more values than months, to one chunk per calendar month, also when -ChunkColumn is given explicitly. The chunk filter stays a range on the bare column (BOOKDATE >= 20260100 AND BOOKDATE < 20260200, the date equivalent, or LIKE '202601%'), so an index on the column is still used for a seek. -ChunkGranularity Value keeps one chunk per distinct value; Month on a column without date values stops with a clear message.
Constraint handlingForeign keys, indexes, and triggers are disabled once for the whole chunked run and rebuilt once at the end, not per chunk. Rebuilding an index is a whole-table operation regardless of the chunk size, so doing it per chunk instead of once is the difference between minutes and hours on a large table.
Reads each chunk by seekOn a heap, or a clustered index that does not lead with the chunk column, SQL Server answers WHERE <chunk range> on a large table with a full table scan, even when an index on the chunk column exists, so every chunk read the whole source table, and the destination's INSERT BULK session sat in ASYNC_NETWORK_IO while the scan passed other chunks' rows. Since 0.1.23.0 -SourceAccess Auto reads each chunk WITH (FORCESEEK) over an index leading with the chunk column (from 4 chunks on, after a probe that the seek can be built). Measured end to end on a lab heap with 358 day chunks: about 30 s per chunk by scan, about 6 s by seek; the gap grows with table size.
No connection leakUp to 0.1.22.0 every chunk left one connection open until the process ended. After about 100 chunks the connection pool (default size 100) was exhausted and every further chunk failed after a 15-second wait. Fixed in 0.1.23.0: the session count stays flat for any number of chunks.
Fails fastWhen a chunk fails mid-copy (bulk-copy timeout, a constraint violation or a full disk on the destination), the source query is cancelled on the server. Before 0.1.22.0 the reader was closed without cancelling, which reads and discards every remaining row of the chunk first: measured on a lab instance, a failure after 15,000 of 600,000 rows took 313 seconds to surface, now 5 seconds.
Column-safe by constructionEach chunk's SELECT is bulk-copied with an explicit name-based column mapping (Invoke-sqmDirectBulkCopy), immune to column order or computed columns on either side, and independent of which dbatools version happens to be installed.
Columnstore-safe batchingA destination with a columnstore index gets its effective batch size capped below the 102,400-row threshold at which SQL Server compresses a batch directly into a rowgroup instead of routing it through the delta store, expensive, and synchronous in the load path on COLUMNSTORE_ARCHIVE. Detected automatically, no configuration needed.
Renaming on the way in-DestinationTable loads into a differently-named destination, such as a freshly re-partitioned "_New" copy of a table ahead of a rename-swap cutover.
Cheap verificationThe final consolidated row-count comparison reads SQL Server's own partition metadata instead of scanning, accurate once the run has actually finished, with no COUNT(*) cost at any table size.

A plain Invoke-sqmTableTransfer call on a table above a configurable row-count threshold (default 10 million, Set-sqmTransferConfig -LargeTableRowThreshold) warns instead of silently doing the all-or-nothing copy, with a ready-to-paste Invoke-sqmChunkedTableTransfer command, including a suggested -ChunkColumn picked from the table's date-typed columns by naming convention. That warning only fires once the destination already holds a meaningful share of the source's rows (default 30%, Set-sqmTransferConfig -ChunkAdviceMinExistingPercent), since chunking's advantage is resumability, on a fresh/empty destination there's nothing to resume, and the plain copy is simply faster. The GUI runs the same check before a plain transfer starts; its transfer mode (Automatic / Plain / Chunked) also offers the chunked path directly.

Reading the waits during a large copy

SqlBulkCopy reads the source through the client and writes it back to the destination. If the writing session (INSERT BULK) waits on ASYNC_NETWORK_IO, the destination is waiting for the client: check the source with Docs/Diagnose-ChunkTransfer-Quelle.sql (scan or seek per chunk). The reading session showing ASYNC_NETWORK_IO for a long time is normal: it waits for the client because writing is slower than reading. The bottleneck shows on the writing session (INSERT BULK): WRITELOG or log growth (FULL recovery logs every row), PAGEIOLATCH (storage), LCK_M_* (blocking). Start the transfer on the SQL Server host itself, from a workstation every row crosses the network twice. And keep index maintenance or partition SPLITs off the source table while it runs: the reading session holds a schema lock, a waiting DDL statement blocks everything queued behind it.

Reference

Seventeen functions, two orchestrators, fifteen building blocks.

FunctionPurpose
Invoke-sqmTableTransferMain entry point, orchestrates the full five-step sequence for one or more tables
Invoke-sqmChunkedTableTransferFor huge tables without a primary key, splits by a column and transfers/resumes one chunk at a time
Get-sqmChunkColumnCandidateRanks candidate chunk columns (date types, period names, YYYYMMDD surrogates) by naming convention and estimated chunk count, and suggests month granularity for day-level columns, from statistics only, no table scan
Export-sqmTableSchemaScripts table DDL from a source instance (SMO Scripter)
New-sqmTableFromScriptExecutes scripted DDL batches against a target instance
Copy-sqmTableSchemaConvenience wrapper: export + create in one call
Disable-sqmTableConstraintsDisables FKs / non-clustered indexes / triggers on a table
Enable-sqmTableConstraintsRe-enables (rebuilds) previously disabled FKs / indexes / triggers, re-detects state, nothing to pass in
Copy-sqmTableDataBulk-copies table data, name-based column mapping, dbatools-version independent, batch size capped automatically on columnstore destinations
Sync-sqmTableDataSyncs a table's actual insert/update/delete delta via a staging table, instead of a full re-copy
Compare-sqmTableRowCountCompares row counts source vs. target for one or more named tables
Compare-sqmDatabaseRowCountCompares row counts for every table between two databases at once, no table list required
Export-sqmTransferReportBuilds the per-run HTML summary/row-count report
Export-sqmDatabaseComparisonReportBuilds the consolidated database-wide comparison report
Show-sqmTableTransferGuiWinForms GUI for the whole workflow
Get-sqmTransferConfig / Set-sqmTransferConfigModule configuration (log path, batch size, large-table threshold, etc.)

Clustered indexes are never disabled, doing so blocks table access entirely, only non-clustered indexes are touched. Foreign keys and triggers are disabled/enabled individually by name, leaving CHECK/DEFAULT constraints untouched.

Quick start

Install, then one call, or the GUI.

# Installation - auto-detects AllUsers (if Admin) or CurrentUser
Install.cmd

# Transfer two tables, scripting metadata and truncating the target first
Invoke-sqmTableTransfer -Source SQL01 -SourceDatabase Sales -Destination SQL02 -DestinationDatabase Sales -Table 'dbo.Orders', 'dbo.Customers' -ScriptMetadata -Truncate -Confirm:$false

# Resume an interrupted run over the same table list - already-matching tables are skipped
Invoke-sqmTableTransfer -Source SQL01 -SourceDatabase Sales -Destination SQL02 -DestinationDatabase Sales -Table $allTables -ScriptMetadata -SkipCompleted -Confirm:$false

# A 300M-row table with no primary key, split by a reporting-date column
Invoke-sqmChunkedTableTransfer -Source SQL01 -SourceDatabase Sales -Destination SQL02 -DestinationDatabase Sales -Table dbo.FactResults -ChunkColumn Dat_ReportDate -Confirm:$false

# Same table, but let the module pick the chunk column and chunk count from statistics
Invoke-sqmChunkedTableTransfer -Source SQL01 -SourceDatabase Sales -Destination SQL02 -DestinationDatabase Sales -Table dbo.FactResults -Confirm:$false

# INT column with YYYYMMDD values: detected automatically, one chunk per month instead of per day
Invoke-sqmChunkedTableTransfer -Source SQL01 -SourceDatabase Sales -Destination SQL02 -DestinationDatabase SalesArchive -Table dbo.Bookings -ChunkColumn BOOKDATE -Confirm:$false

# Or via GUI
Show-sqmTableTransferGui

Configuration is persisted separately from sqmSQLTool (%APPDATA%\SQLDataTransfer\config.json) so both modules can be imported side by side without interfering, but LogPath/OutputPath default to the same location sqmSQLTool uses.

Next steps

Move your first table today.

Built on dbatools, if it's already on the box, sqmDataTransfer is one Import-Module away.